Private assistants
Chat and retrieval assistants served inside your network with vLLM or llama.cpp, so prompts and documents never leave your infrastructure.
LLaMA is a family of open-weight models you can run on your own hardware or private cloud. We choose it when data cannot leave your environment, when you want to fine tune on your own material, or when you need control over how inference runs.
A short call. Your first build, a fixed quote, and the timeline. No obligation.
Chat and retrieval assistants served inside your network with vLLM or llama.cpp, so prompts and documents never leave your infrastructure.
Task-specific adapters trained with LoRA or QLoRA on your labelled examples, producing a smaller model that follows your format reliably.
Models quantised to fit available GPUs or even CPU-only machines, with quality checked against the full-precision version.
Overnight classification and summarisation runs over large archives on hardware you already own.
Often paired with
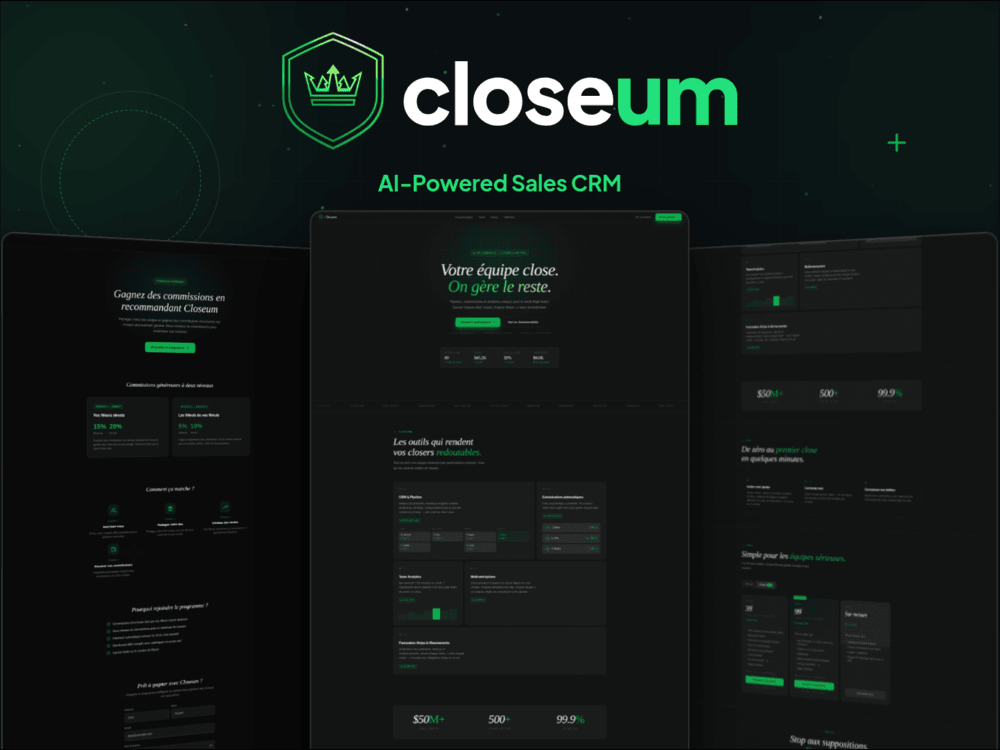
13+ connected modules from calls through commissions
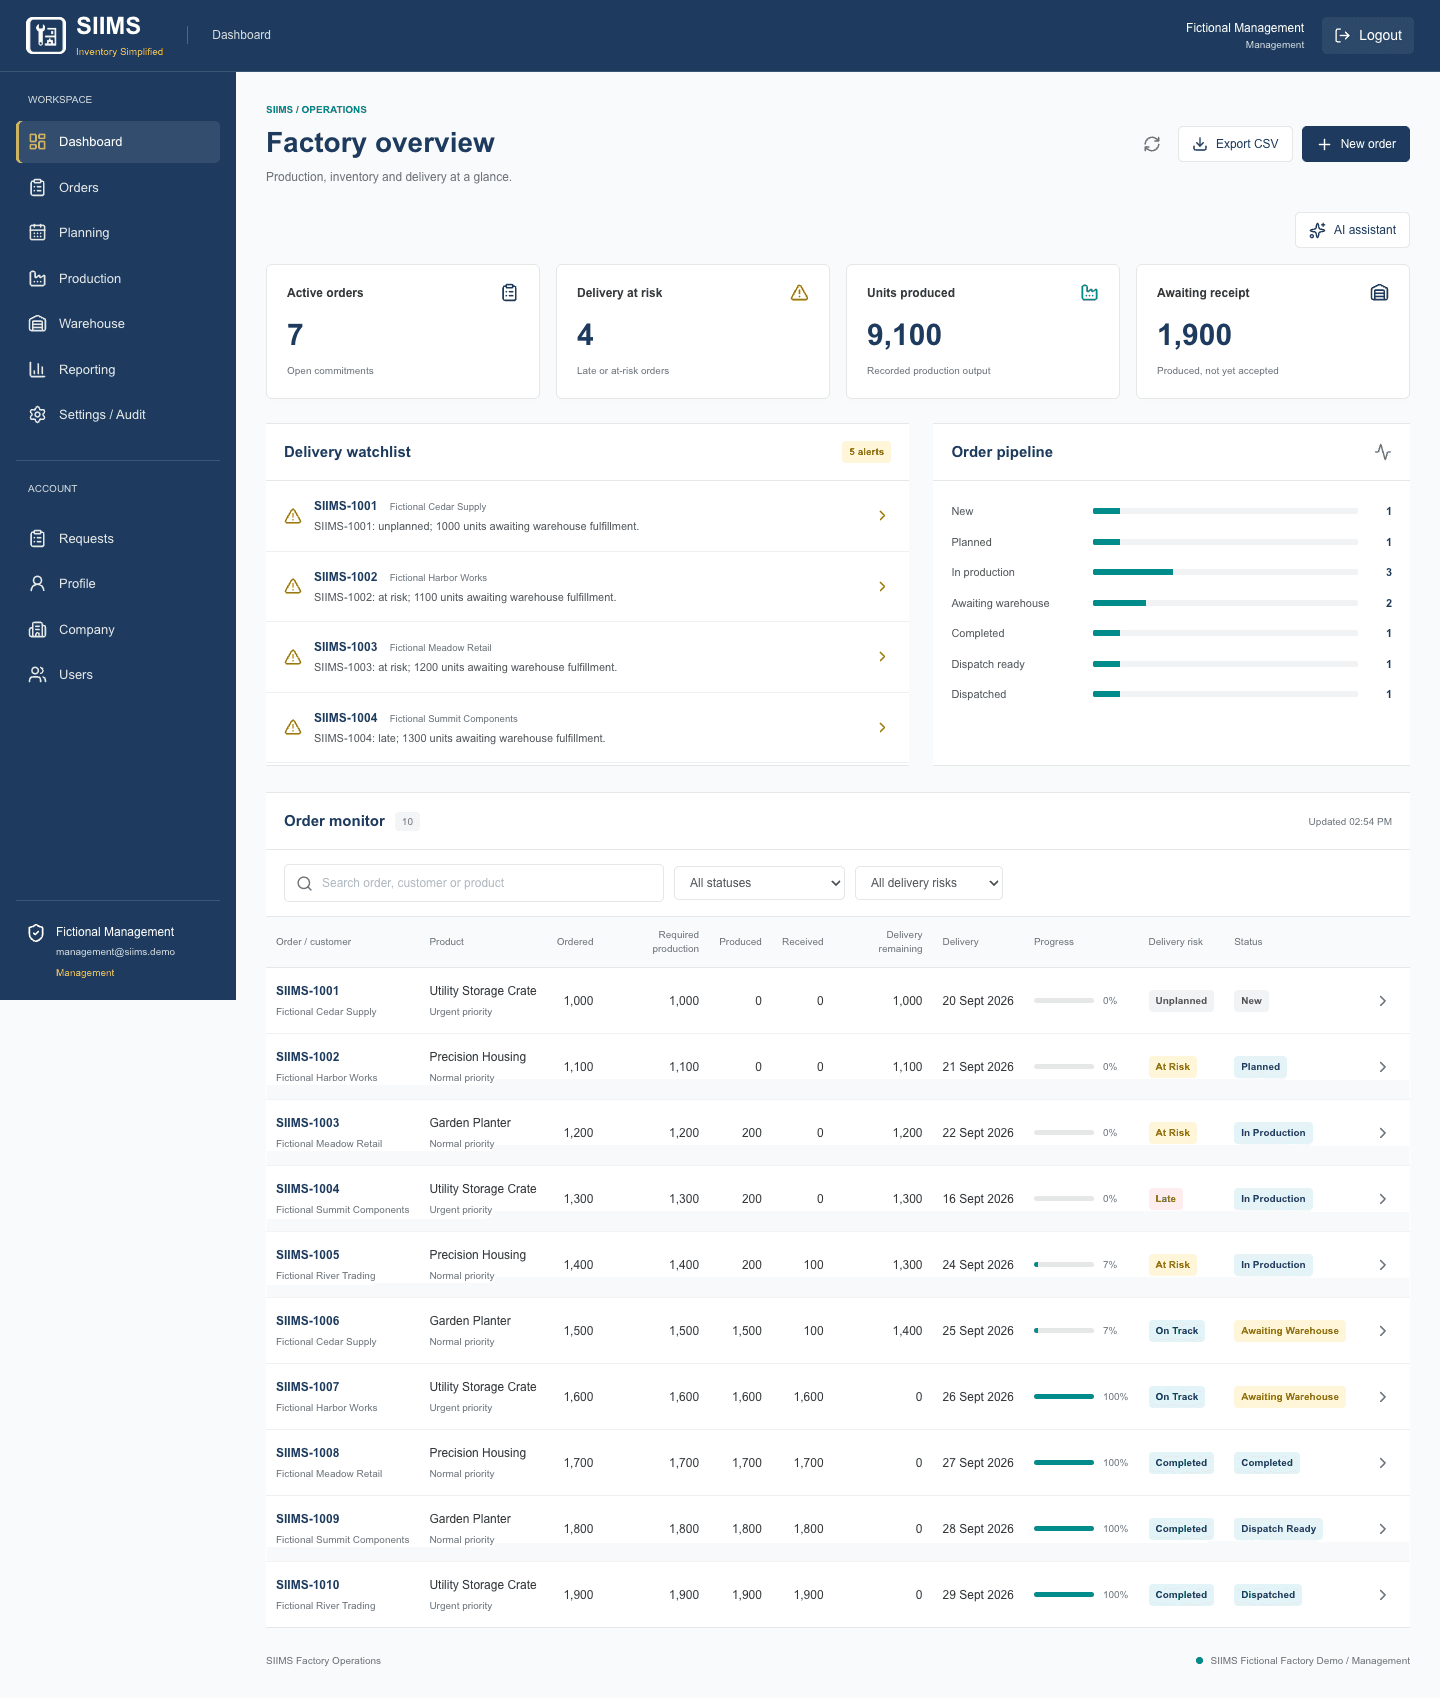
Orders, production, warehouse, and dispatch on the same records
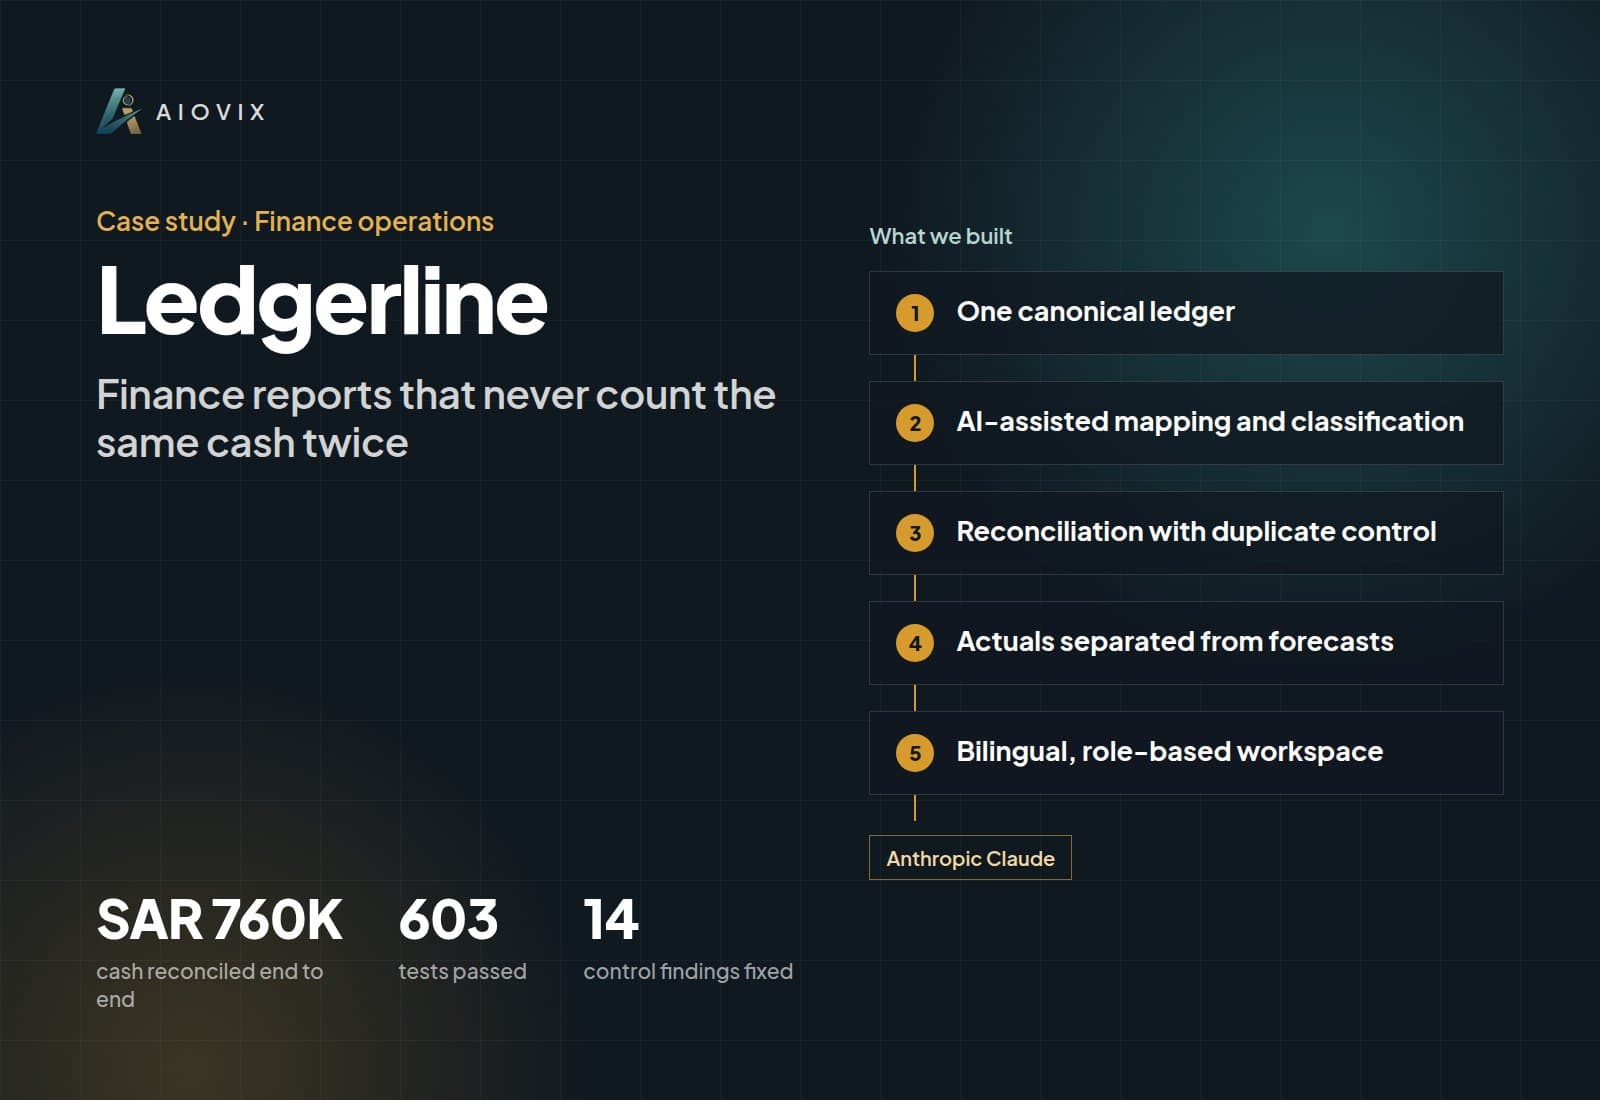
603 tests passed in a dated financial-control verification
For decent speed, usually yes, either owned or rented from a cloud provider. Smaller or quantised models can run on modest hardware for low-volume internal use.
Open-weight models come with licence terms that differ by release. We read the terms for the specific model before recommending it for your use case.
When prompting and retrieval cannot get you consistent output on a narrow task and you have good labelled examples. Otherwise we start with prompting and retrieval, which is cheaper to maintain.
Private deployment, Fine tuning, Cost-controlled inference, On-premise AI, and related work. We choose LLaMA when it is the right fit for the product, the team and the budget.
Yes. We can review what you have, fix what is fragile, and extend it, or build alongside your team.
Where we apply it
Book a short call and show us one workflow. You leave with what we would build first, a fixed quote, and what should wait.