Multilingual support bots
Assistants that answer in Chinese, English, Arabic and other languages from one self-hosted model, with retrieval over your help content.
Qwen is an open-weight model family with strong multilingual coverage and a range of sizes, including coding-focused variants. We use it for self-hosted assistants where several languages matter and where a smaller model needs to punch above its weight.
A short call. Your first build, a fixed quote, and the timeline. No obligation.
Assistants that answer in Chinese, English, Arabic and other languages from one self-hosted model, with retrieval over your help content.
Internal code review and generation helpers running on Qwen coding variants, kept inside your network.
Tuned smaller checkpoints that handle tagging, routing and extraction at high volume on modest GPUs.
Reading charts, receipts and screenshots with the vision-capable variants served through an OpenAI-compatible endpoint.
Often paired with
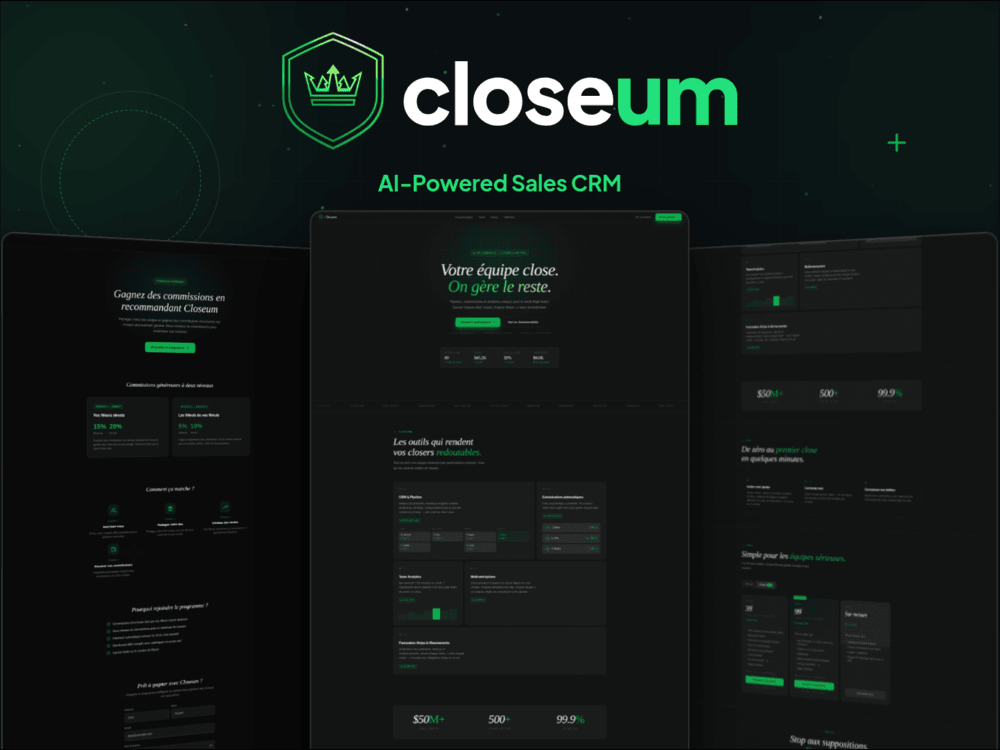
13+ connected modules from calls through commissions
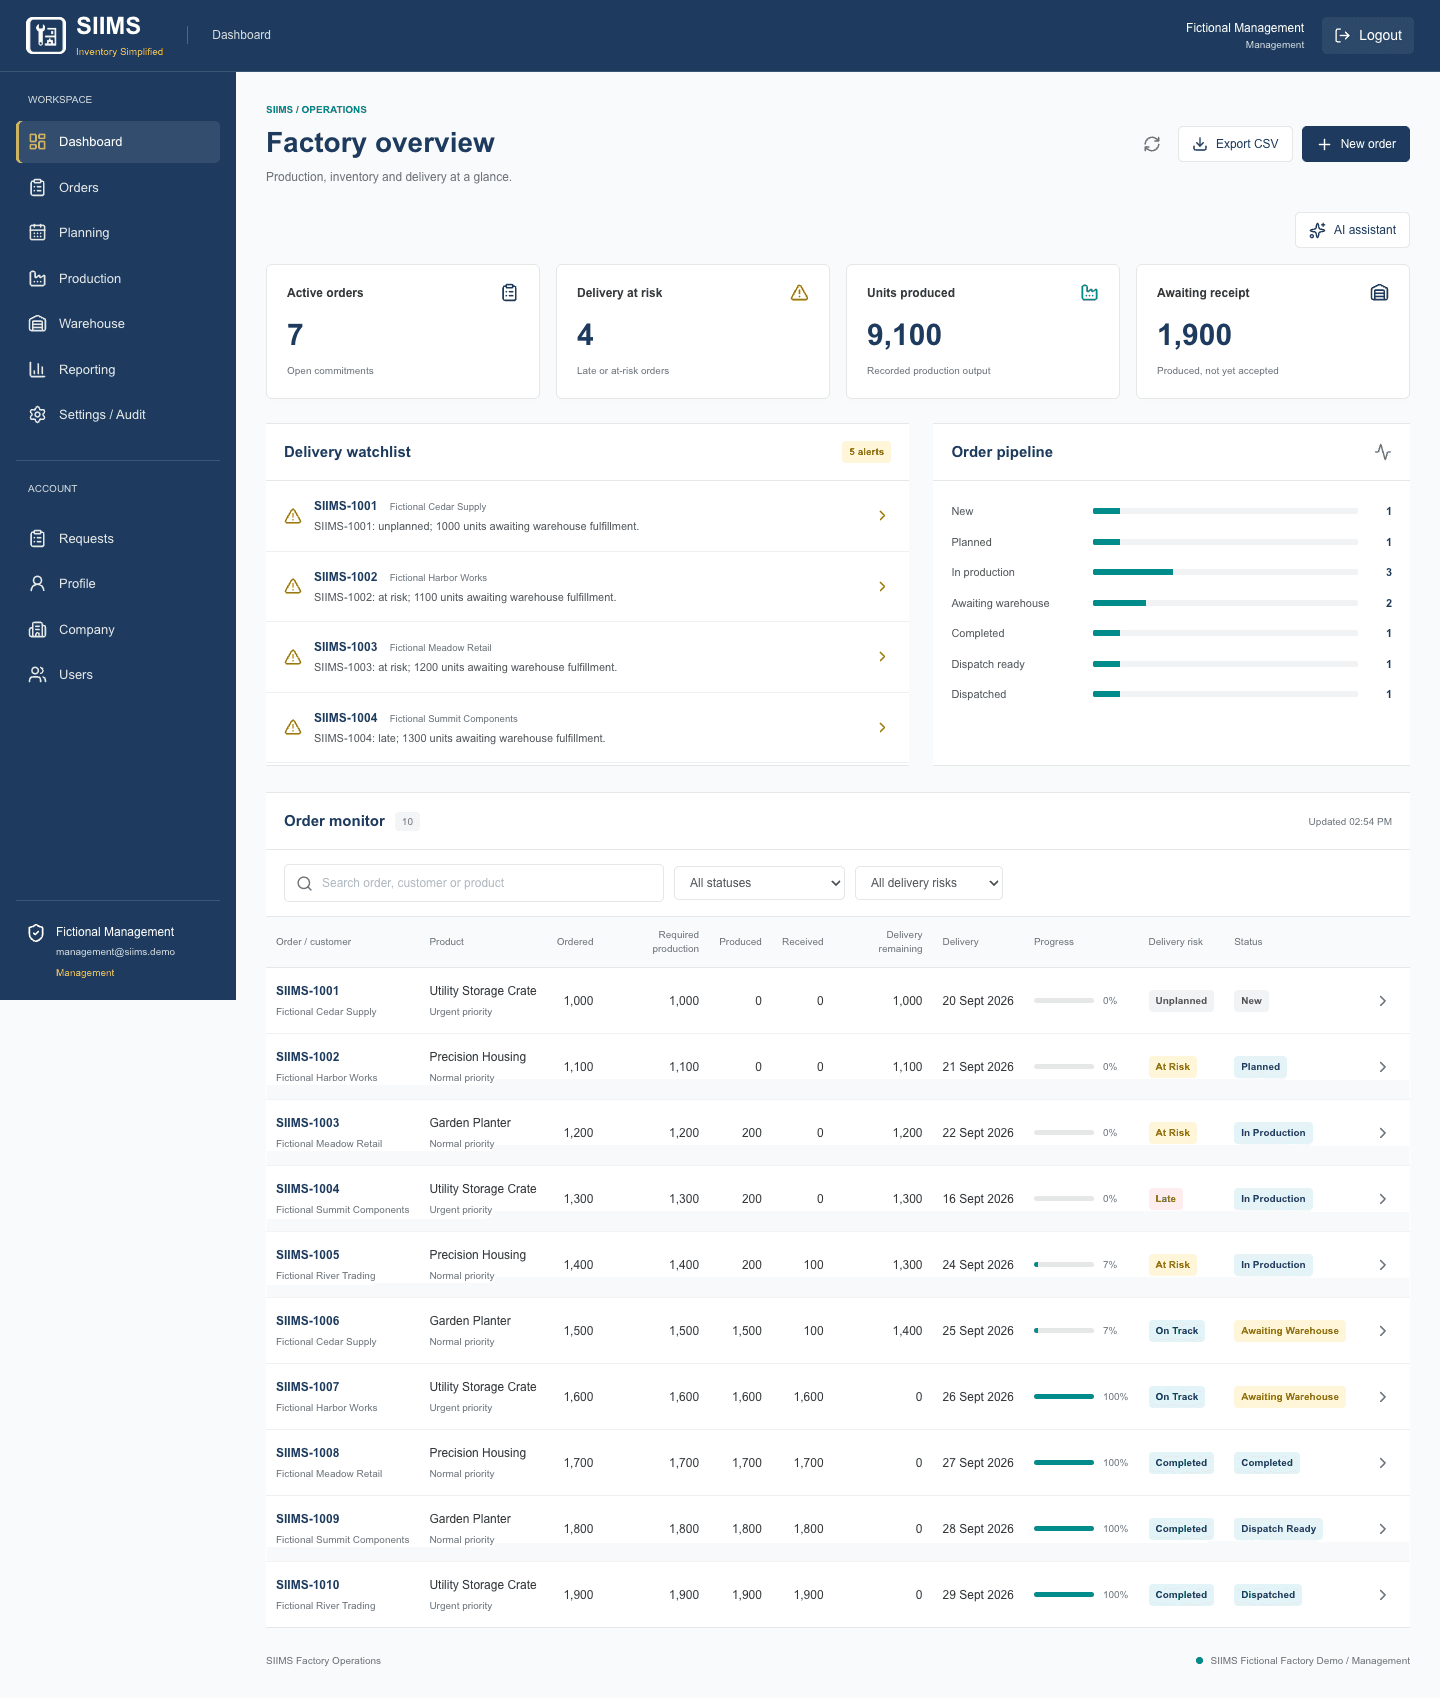
Orders, production, warehouse, and dispatch on the same records
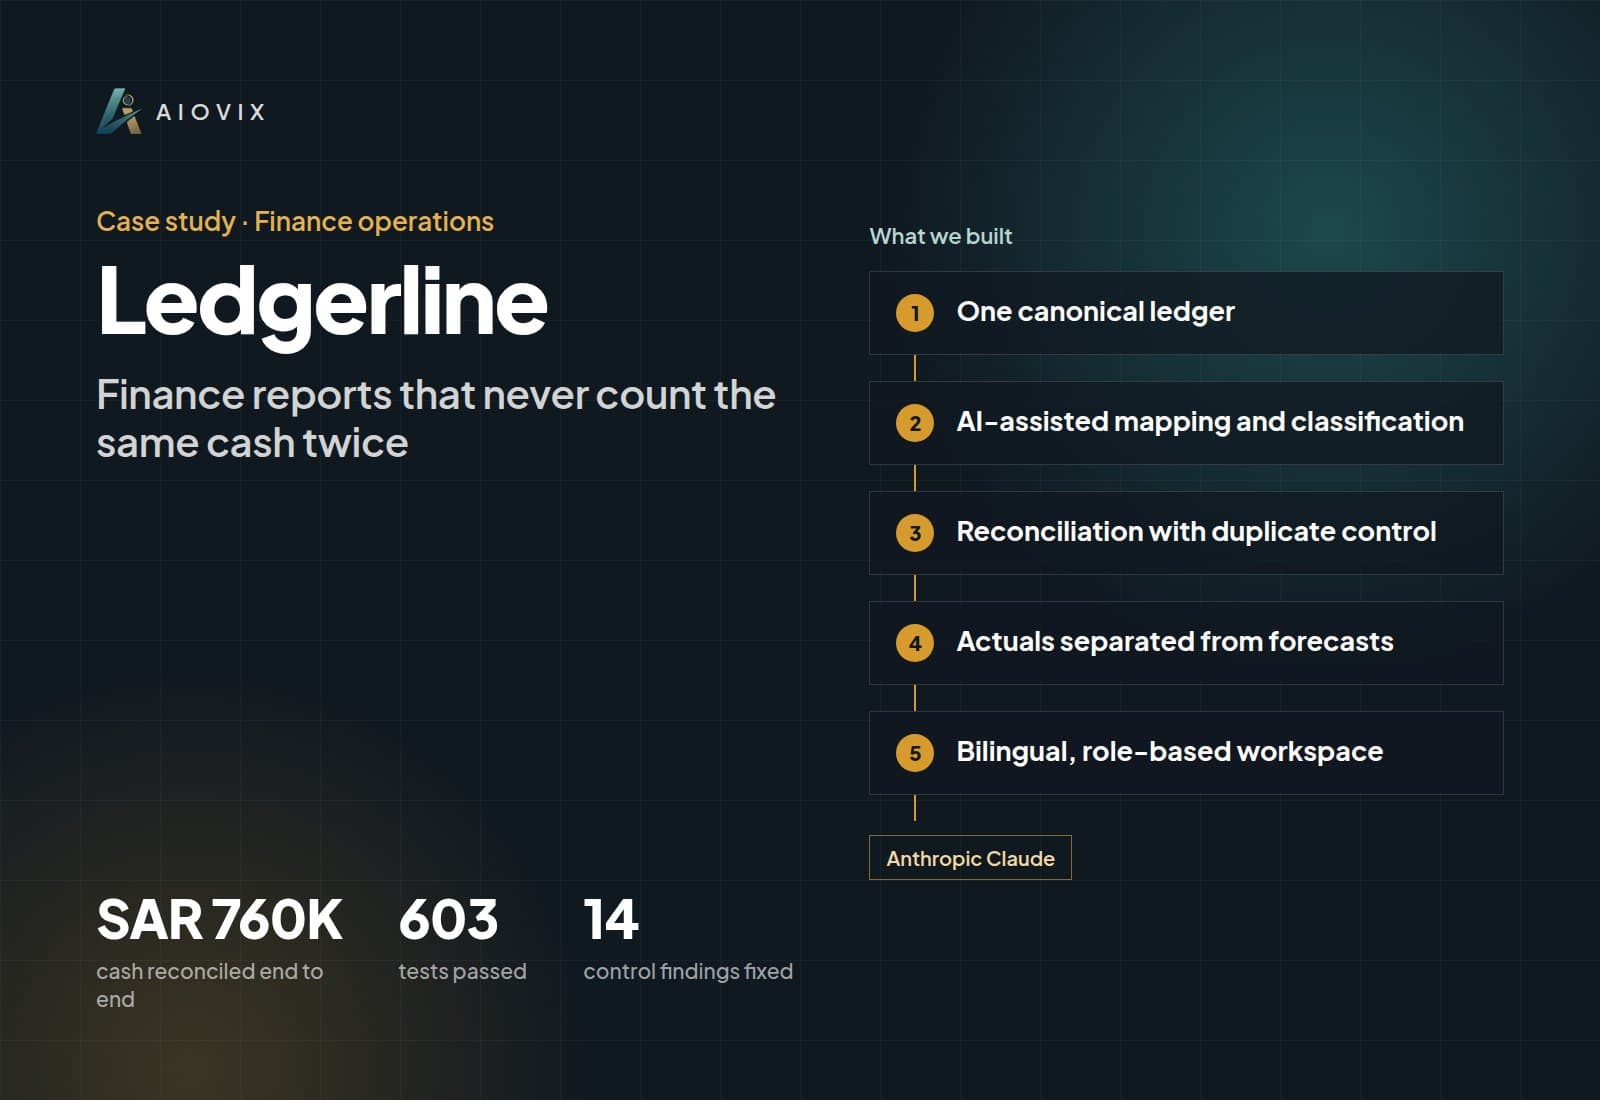
603 tests passed in a dated financial-control verification
It depends on your task and languages. We run a small head-to-head test on your own examples and choose on evidence.
Yes. Serving engines such as vLLM expose an OpenAI-compatible endpoint, so application code can switch between hosted and self-hosted models with little change.
Often not. The base models cover many languages well, and we only tune when testing shows a gap in your domain vocabulary or output format.
Self-hosted models, Multilingual assistants, Fine tuning, Cost-efficient inference, and related work. We choose Qwen when it is the right fit for the product, the team and the budget.
Yes. We can review what you have, fix what is fragile, and extend it, or build alongside your team.
Where we apply it
Book a short call and show us one workflow. You leave with what we would build first, a fixed quote, and what should wait.